 THE CURIOUS SIDE OF AI
AI News
AiBrainWorX Model Launcher: New Controls, Linux Updates and a 45.1 Tok/s Cached Test
AI Assisted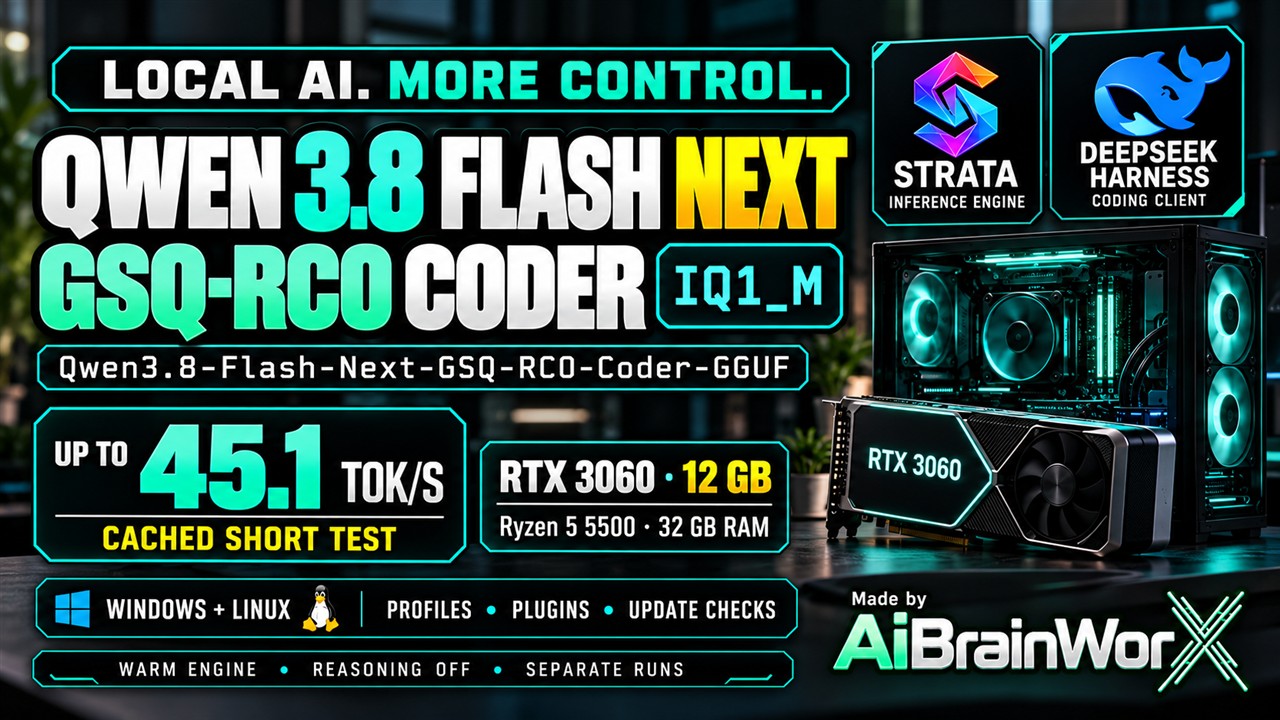
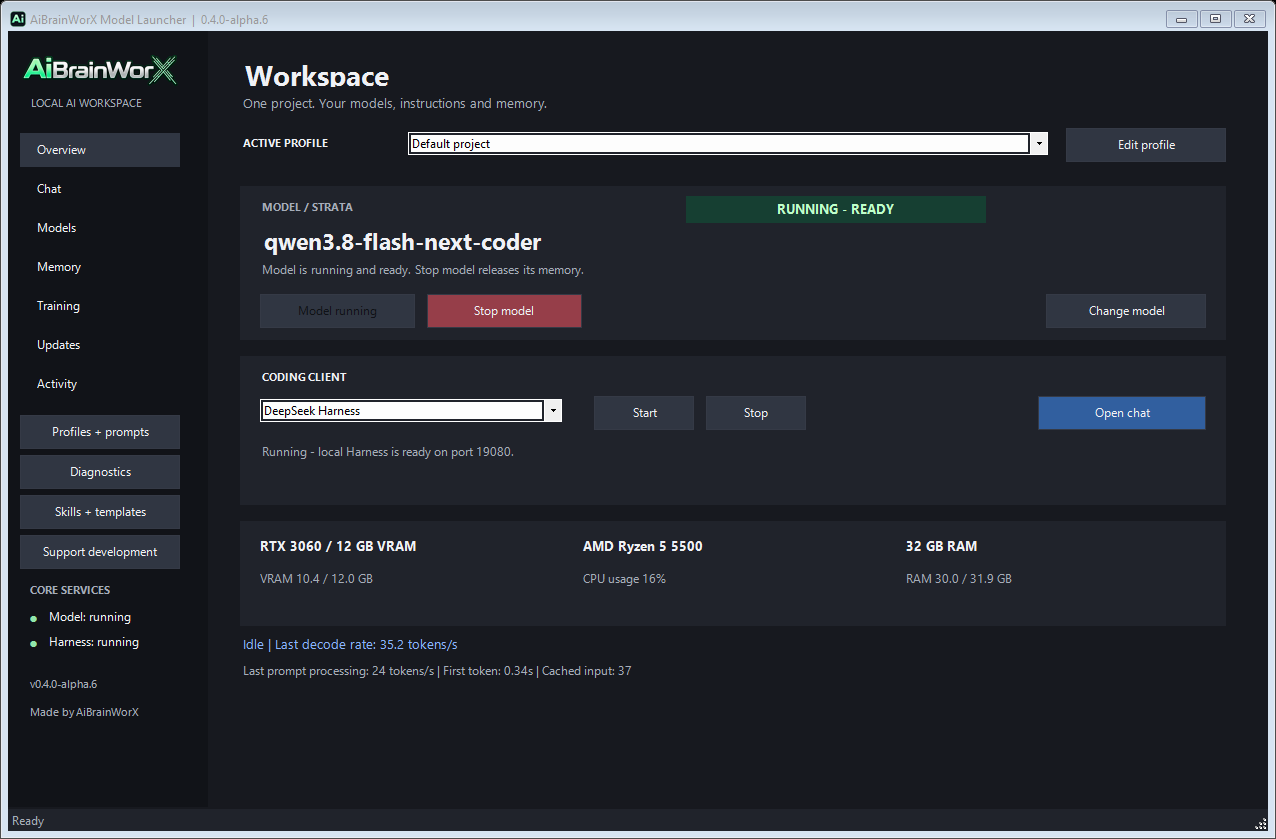
Local AI should be easier to operate, inspect and customize. Our latest AiBrainWorX Model Launcher update adds clearer service lights, visible progress and extensions you can switch without restarting the launcher.
Windows 0.4.0-alpha.6 and the separate Linux 0.1.0-alpha.2 repository are now on GitHub. Strata supplies inference; DeepSeek Harness supplies the coding workspace. Using Harness does not mean these tests ran a DeepSeek model.
More control, without another heavy background workload
The larger Windows workspace and native Linux browser interface now include labeled model/Harness indicators and an optional Activity plugin. Light monitoring reuses existing telemetry while its page is visible. Process inspection is an explicit read-only action. Plugins can be disabled, archived, restored and reapproved without stopping the model; their private data stays outside application updates.
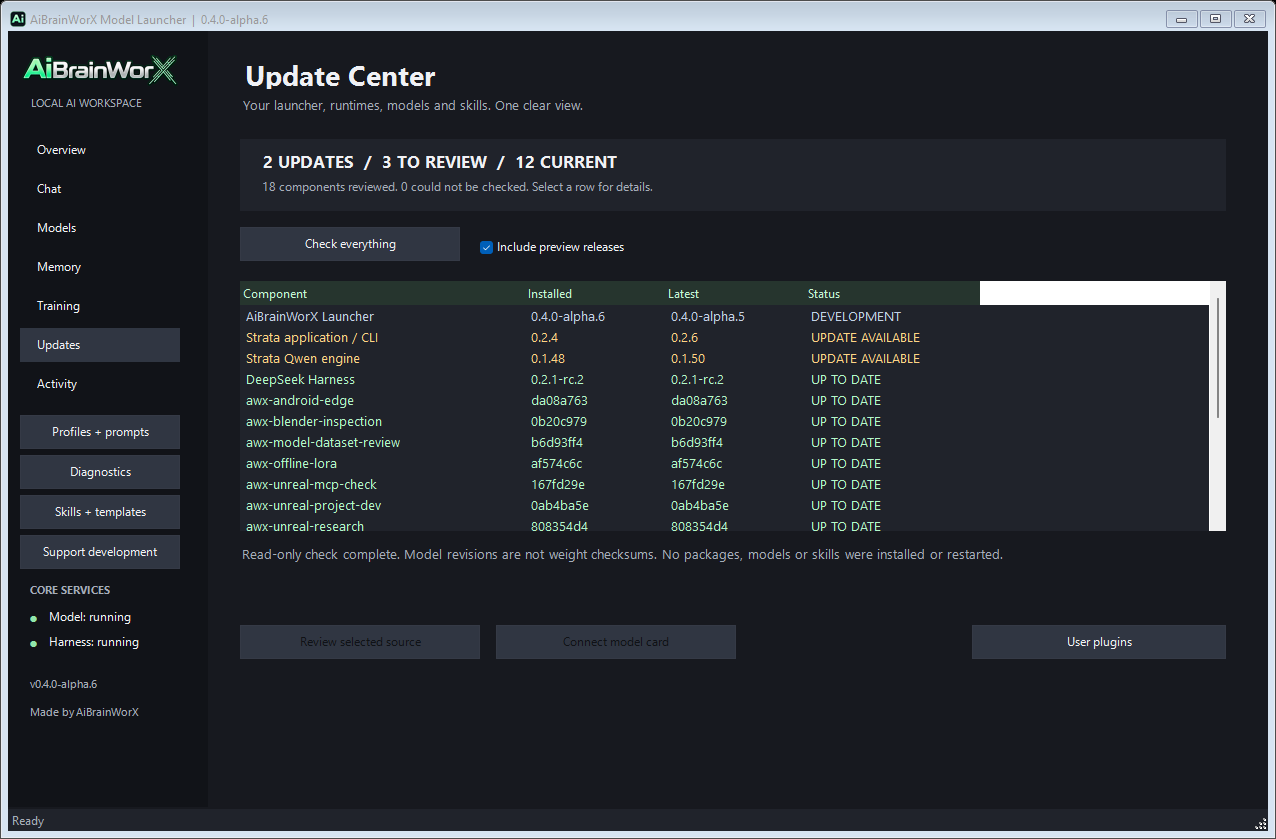
Update checks show actual completed jobs. Windows setup adds real per-transfer download bars, unknown-size indicators, helpful source comments and a public-output mode that masks private paths. Checking for updates does not silently replace models, skills or customizations.
45.1 tokens/s — what we actually measured
On our RTX 3060 12 GB, Ryzen 5 5500 and 32 GB RAM, Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF, IQ1_M, through Strata application 0.2.4 / engine 0.1.48 produced 35.7, 45.1 and 44.5 decode tokens/s in the three monitored runs.
These were identical short coding requests on a warm Windows engine, with 37 cached input tokens, temperature zero and reasoning off. The monitored replies each completed normally at 243 output tokens. The alternating unmonitored runs also warmed up, so this small comparison does not prove monitoring improved speed. It is not an uncached, sustained-throughput or Linux benchmark. One unmonitored reply hit its output cap; the full table remains in our validation notes.
A real separate install test
Setup installed 617 official client packages into a fresh private runtime using existing Python and Node. The authenticated Harness page, isolated gateway and a native-budgeted PONG reply worked. Two bounded coding replies also completed through the guarded gateway. The original launcher configuration remained unchanged. We reused installed engine/model files; we did not redownload 58.4 GB of weights or claim a fresh-machine prerequisite install.
Validation includes 135 Windows Python tests (one platform-permission skip), 135 native Ubuntu WSL tests without skips, nine frontend contracts and PowerShell UI/setup/config-isolation checks. Real process sampling worked on both systems; those screens remain private.
Get the code and the technical details
Windows repository · Separate Linux repository · Full validation record.
Original launcher code is MIT. External tools and model weights keep their own licenses. Made by AiBrainWorX.