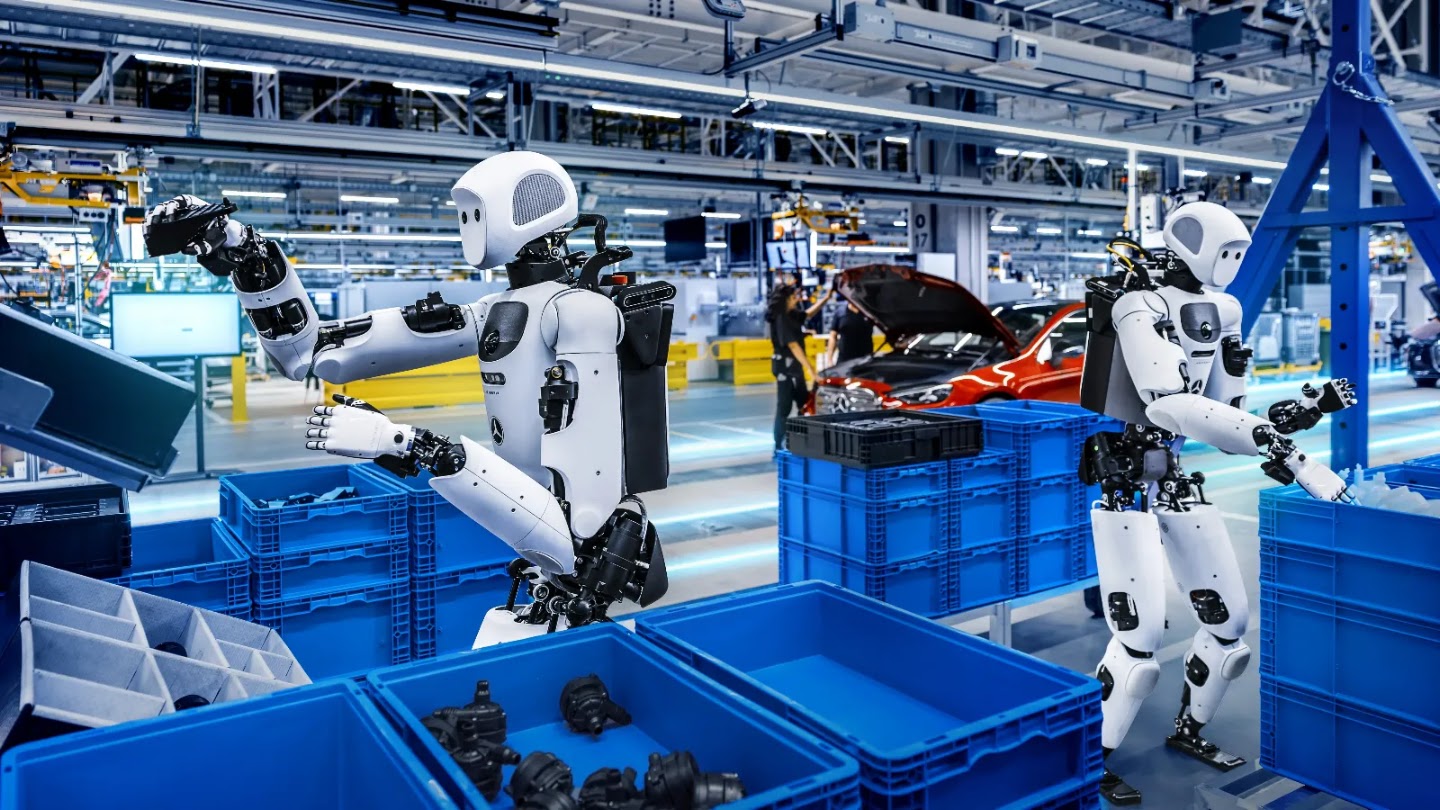
Google DeepMind has introduced Gemini Robotics 2.5, a vision-language-action model it says is rolling out to robotics partners. The November 10 announcement describes evaluations across more than 200 tasks and a proof of concept with Apptronik and Mercedes-Benz.
From a test to a factory floor
Google says Apollo 2 robots used the model to sort automotive parts into organized trays at production sites in Hungary and Germany. It reports a 96% success rate for the described kitting task. That is a company-reported result for a particular pilot, not an independent measure of reliability across all factory work or a guarantee of safe operation.
The model family connects visual observations and instructions to robot actions, while an embodied-reasoning component tracks the workflow. Google also describes safety guidance and an adversarial evaluation benchmark. Such tests matter, but physical safety depends on the whole system, deployment environment and independent assessment—not just model scores.
What is available
Google describes a rollout to robotics partners, not a broadly downloadable consumer model. Its examples range from manipulating tools and flexible objects to industrial sorting. The breadth is interesting, but the announcement does not establish that a single robot can perform every depicted task reliably in arbitrary workplaces.
We have not tested the model, witnessed the pilot or independently validated the reported results.
Original reporting based on linked primary sources; no independent hardware, model or benchmark test.