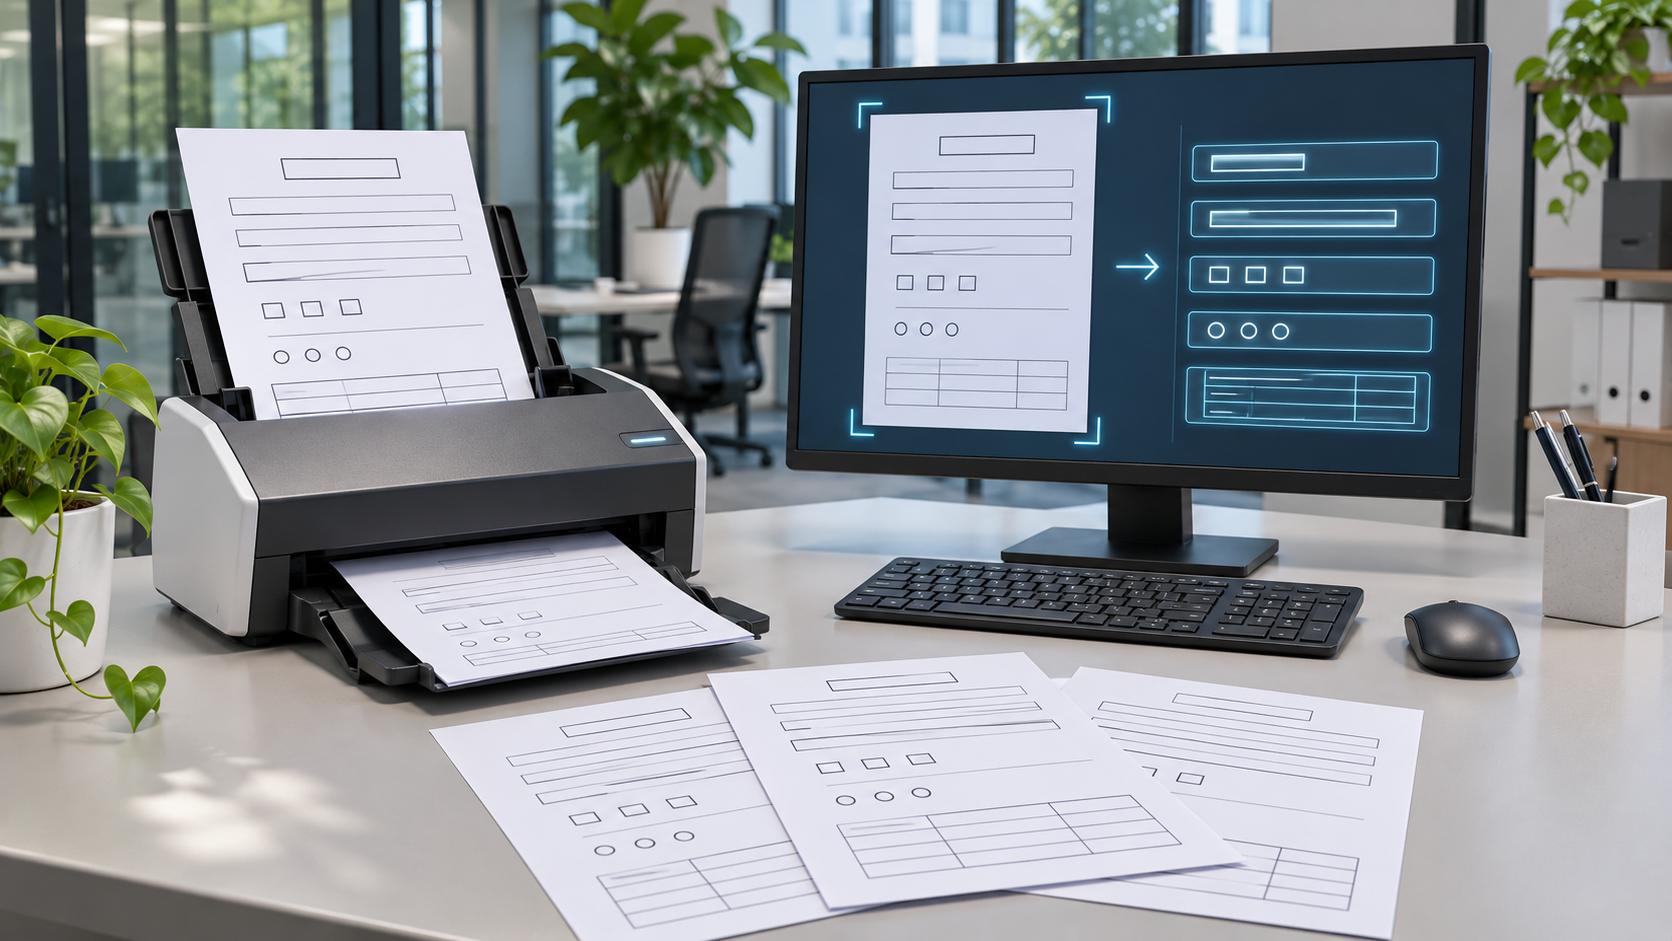
Dharma-AI has described a 2-billion-parameter document model designed to return structured fields as JSON. Its developer report describes both open extraction and requests for a specific schema. The report appeared November 4; this article was published November 8.
Specializing for a narrower job
The team says the extractor builds on DharmaOCR-LITE and can identify fields and tables or fill a supplied schema. Returning machine-readable output is useful for document workflows, but applications still need to validate values against the actual document and manage sensitive information appropriately.
Dharma reports a 0.834 score on its own composite extraction benchmark, compared with 0.816 for one Claude configuration and 0.741 for one GPT configuration. Those results, test set and cost comparison are the developer's, not an independent assessment. A narrow benchmark does not show that a small model beats every larger model on every document.
What to verify before adoption
Ask how it handles your document formats, missing fields and private records, and compare total deployment costs at your workload. The report links a demo; we have not confirmed downloadable weights for this specific extractor or tested its accuracy, privacy or hardware requirements.
Original reporting; claims attributed to their sources. No local tests implied.