Tencent has posted final Hy4 model artifacts, including instruction-tuned, FP8 and pretrained base variants. The public repository history records a November 20 UTC upload. This is a material availability change from our earlier report, which covered the product announcement while final weights were still pending.
The official model card, artifact history and code repository now point to the final releases. We checked metadata, cards, file listings and license text; we did not download weights or run inference.
Three artifacts, with different purposes
Hy4 is the instruction-tuned model, Hy4-FP8 is its FP8 quantized variant, and Hy4-base is a pretrained checkpoint rather than a ready-made chat assistant. Our exact profiles link the instruction model, FP8 variant and base checkpoint. Quantization is not a separate foundation-model launch.
Tencent describes a 770B-parameter language backbone with 49B text parameters active per token, excluding additional vision, adapter and drafter components from the headline total. The declared context limit is 1,048,576 tokens. These are publisher specifications, not our capacity measurements.
Read the actual license heading
The distributed license explicitly identifies itself as the Tencent Hy License, version 1.0. Although derived from Apache-2.0, it says it is not that license. The same text was present in the three checkpoint repositories we reviewed.
Its additional commercial section requires a separate written license for specified large model-as-a-service businesses, including stated revenue or monthly-user thresholds. It also defines exclusions and an internal-use exception. Those conditions should be read in full; describing the release simply as Apache-licensed would erase a material distinction.
Our analysis: availability is useful even when terms are conditional
Public weights let researchers inspect an artifact and give deployment teams options beyond a hosted API. That is a meaningful change. It does not mean every deployment is permitted on identical terms or that an enormous mixture-of-experts model is inexpensive to operate.
Active parameters describe which parts participate in processing a token. They do not establish the memory needed to retain the full model and working context. A large maximum context also says little by itself about speed or reliability on a particular long task.
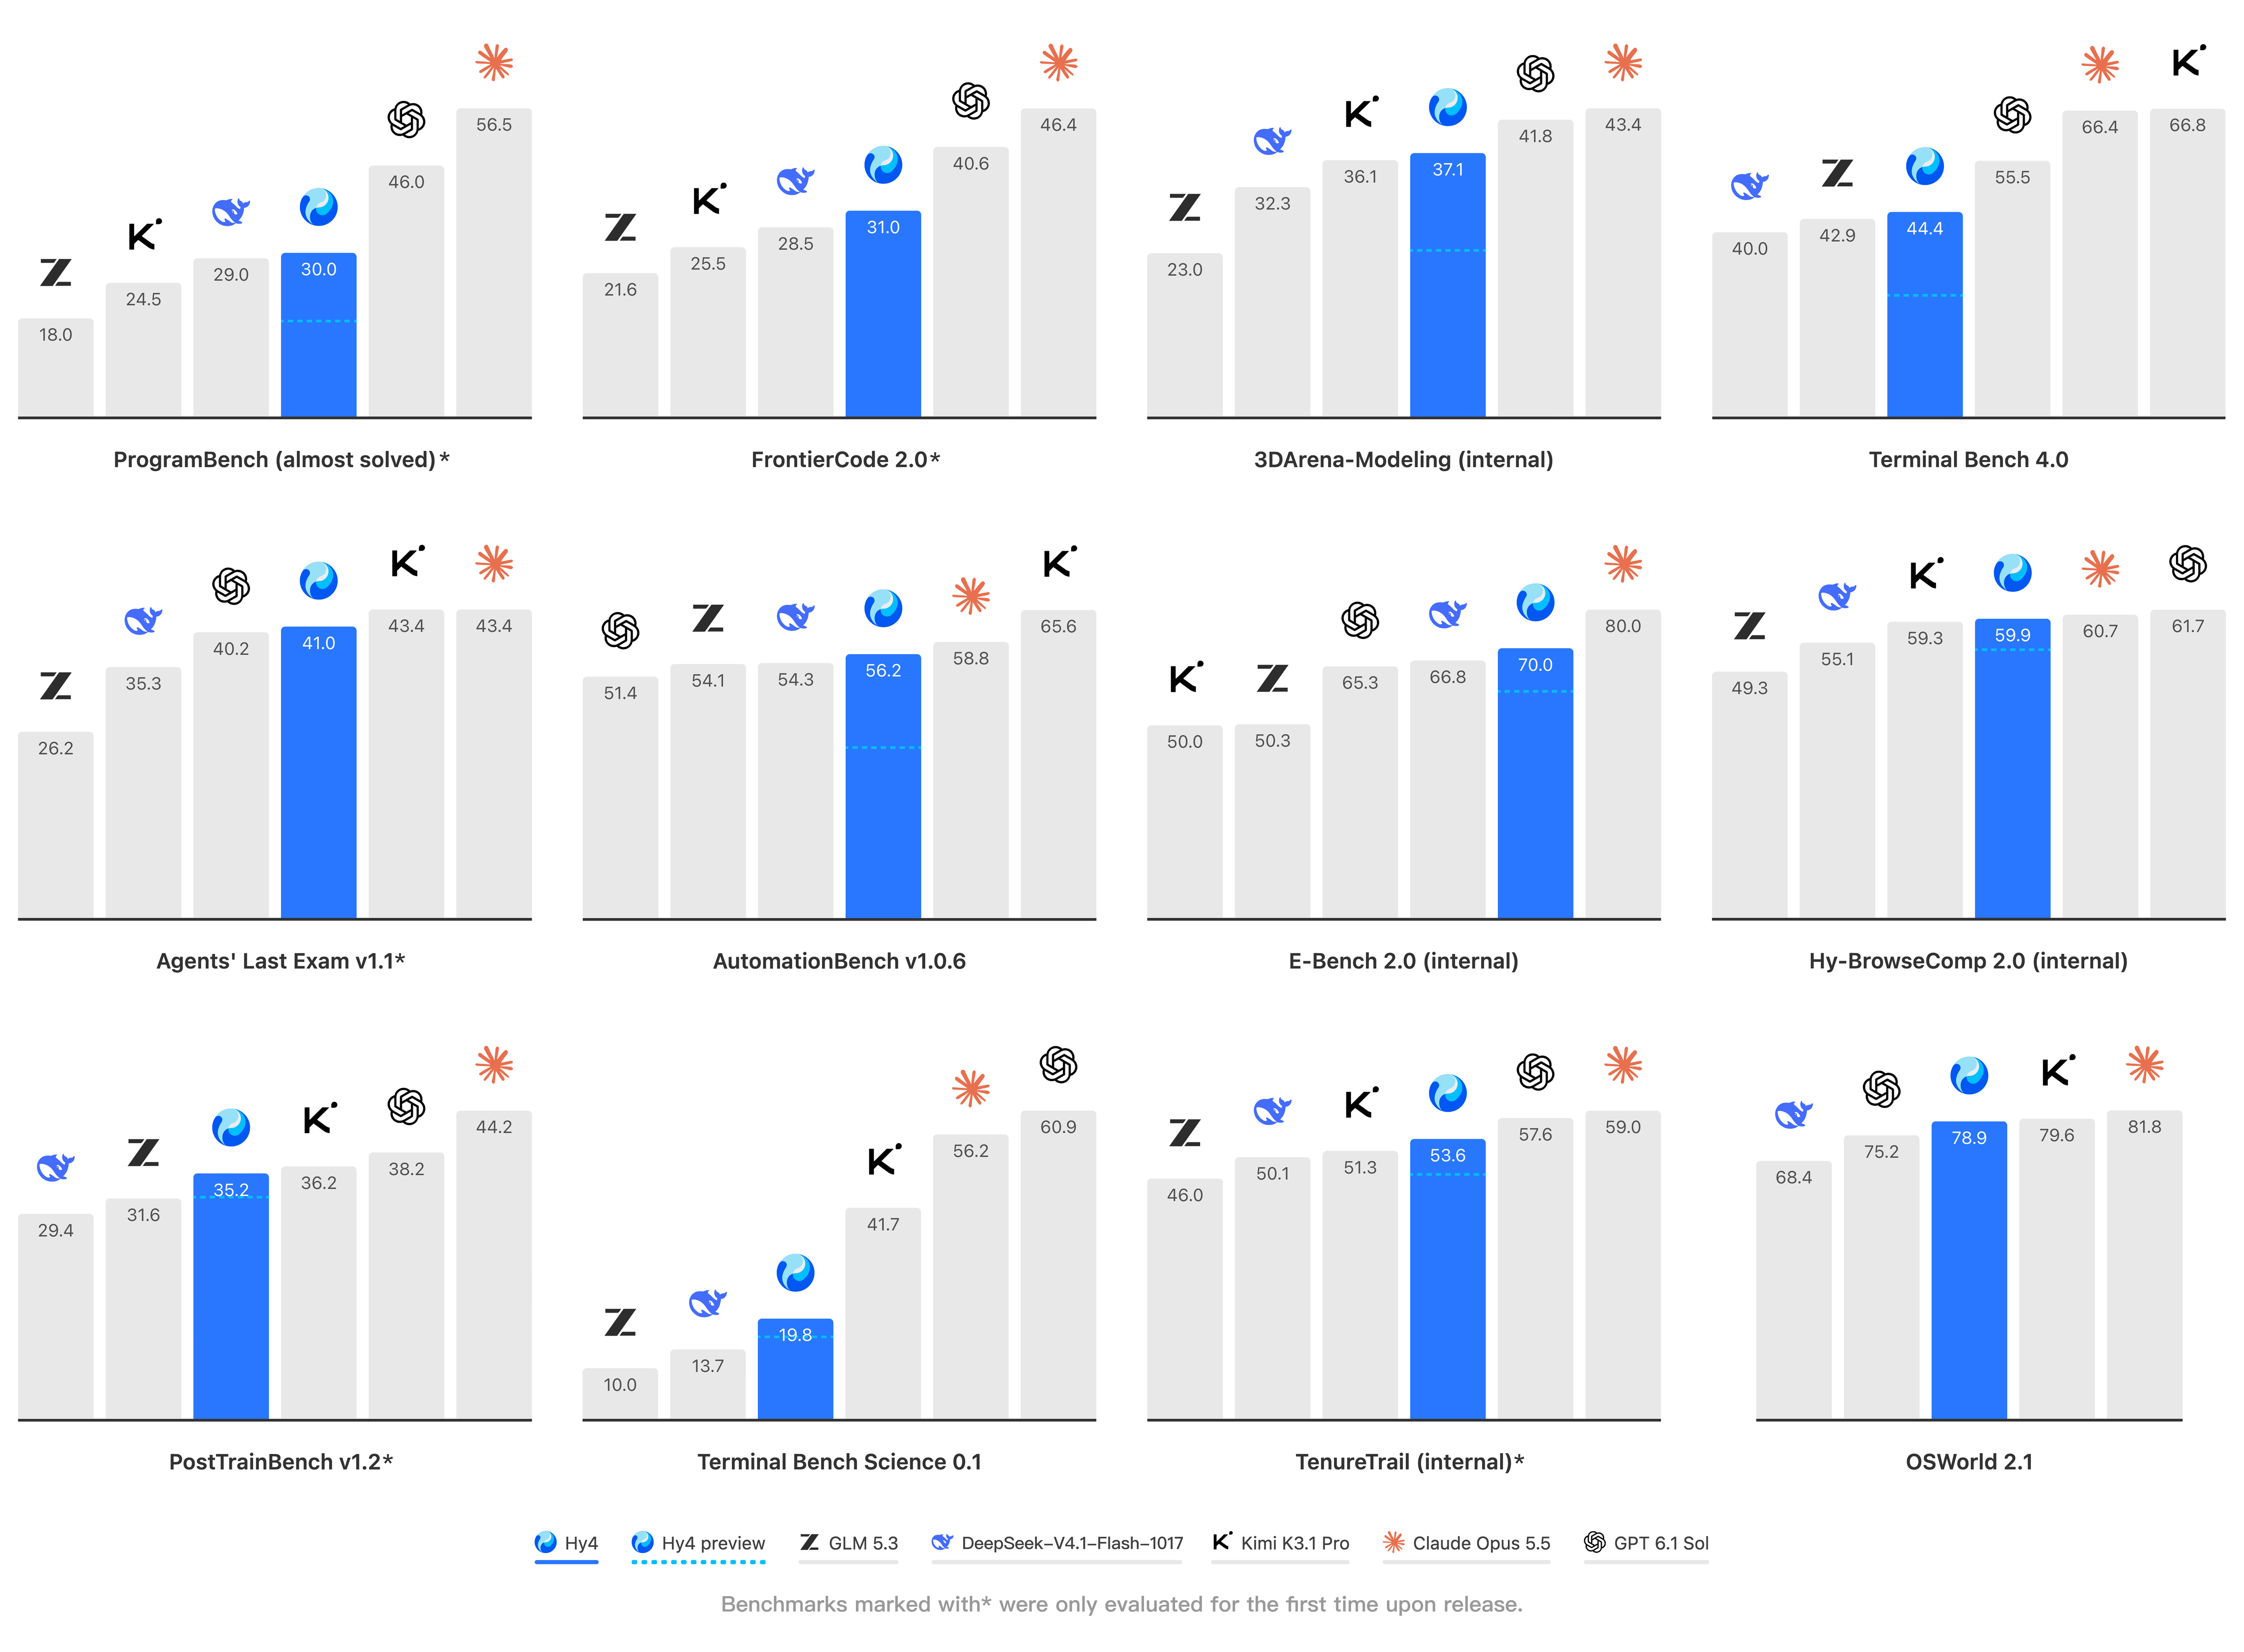
Tencent acknowledges remaining gaps on difficult mathematics, long-horizon coding and advanced visual reasoning. Its comparative results remain publisher evaluations. Our code profile links the implementation for inspection without claiming local compatibility or independent benchmark validation.
EXPLORE THE SOURCE
Projects in this story
GitHub repositories
- Tencent-Hunyuan/Hy4 ↗View project details
Original source and implementation review with labeled editorial analysis. No model inference, installation, paid service, API benchmark or independent security/robotics test performed.